ArchiveBox plugin gallery
Plugins for archiving the web with ArchiveBox or abx-dl.
This gallery collects the workflows that usually take time to wire up by hand: browsers, media tools, parsers, metadata extractors, search indexes, and format-specific outputs. Choose a plugin to see how to run it, what it depends on, and what it produces.
screenshot
pdf
media
metadata
search
html/text
url parsing
Try a plugin in one command
Click a plugin card below and this example updates with the selected plugin.
Expand to see pip install details
pip install abx-dl
abx-dl install
mkdir archive
cd archive
abx-dl 'https://example.com'- Pick some capabilities Filter by features, output types, dependencies, hook phases, or config keys.
- Run the generated command Open a plugin and copy an abx-dl or ArchiveBox command with the right plugin selected.
- Get standard outputs Use known file formats and declared dependencies instead of wiring each extractor by hand.
Catalog
Plugin catalog
Chrome Screencast
chrome_screencast
Stream low-resolution Chrome screencast JPEG frames for the admin live progress UI.
#02
Snapshot
image/jpeg
Chrome Screencast
chrome_screencastStream low-resolution Chrome screencast JPEG frames for the admin live progress UI.
#02
Snapshot
image/jpeg
Stream low-resolution Chrome screencast JPEG frames for the admin live progress UI.
GitHubabx-dl --plugins=chrome_screencast 'https://example.com'CHROME_SCREENCAST_ENABLED=true archivebox add 'https://example.com'
order 90
background (daemon)
CrawlSetup
order 02
background (daemon)
Snapshot
image/jpeg
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
CHROME_SCREENCAST_ENABLEDEnable live browser preview frames for the admin live progress UI |
true |
boolean
|
— |
CHROME_SCREENCAST_QUALITYLive preview JPEG quality |
65 |
integer
min 1 |
— |
CHROME_SCREENCAST_FPSMaximum screencast JPEG frames written per second |
1 |
integer
min 1 |
— |
CHROME_SCREENCAST_KEEPNumber of screencast frames to keep after Chrome exits (there is a separate screenshot plugin for real hi-res screenshots) |
0 |
integer
min 0 |
— |
CHROME_SCREENCAST_SCALECDP screenshot clip scale for live preview frames |
0.5 |
number
min 0.1 |
— |
uBlock Origin Lite
ublock
Install the uBlock Origin Lite extension to block ads, trackers, and other page clutter during archiving.
#12
Snapshot
ublock (env,chromewebstore)
uBlock Origin Lite
ublockInstall the uBlock Origin Lite extension to block ads, trackers, and other page clutter during archiving.
#12
Snapshot
ublock (env,chromewebstore)
Install the uBlock Origin Lite extension to block ads, trackers, and other page clutter during archiving.
GitHubabx-dl --plugins=ublock 'https://example.com'UBLOCK_ENABLED=true archivebox add 'https://example.com'ublock
providers=env,chromewebstore
order 80
foreground
CrawlSetup
order 95
foreground
CrawlSetup
order 11
foreground
Snapshot
order 12
background (daemon)
Snapshot
None
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
UBLOCK_ENABLEDEnable uBlock Origin Lite browser extension for ad blocking |
true |
boolean
|
USE_UBLOCK |
2Captcha
twocaptcha
Install and configure the 2Captcha extension to solve CAPTCHAs during browser-based archiving.
#14
Snapshot
twocaptcha (env,chromewebstore)
2Captcha
twocaptchaInstall and configure the 2Captcha extension to solve CAPTCHAs during browser-based archiving.
#14
Snapshot
twocaptcha (env,chromewebstore)
Install and configure the 2Captcha extension to solve CAPTCHAs during browser-based archiving.
GitHubabx-dl --plugins=twocaptcha 'https://example.com'TWOCAPTCHA_ENABLED=true archivebox add 'https://example.com'twocaptcha
providers=env,chromewebstore
order 80
foreground
CrawlSetup
order 95
foreground
CrawlSetup
order 14
background (daemon)
Snapshot
None
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
TWOCAPTCHA_ENABLEDEnable 2captcha browser extension for automatic CAPTCHA solving |
true |
boolean
|
CAPTCHA2_ENABLED, USE_CAPTCHA2, USE_TWOCAPTCHA |
TWOCAPTCHA_API_KEY2captcha API key for CAPTCHA solving service (get from https://2captcha.com) |
"" |
string
|
API_KEY_2CAPTCHA, CAPTCHA2_API_KEY |
TWOCAPTCHA_RETRY_COUNTNumber of times to retry CAPTCHA solving on error |
0 |
integer
min 0 |
CAPTCHA2_RETRY_COUNT |
TWOCAPTCHA_RETRY_DELAYDelay in seconds between CAPTCHA solving retries |
5 |
integer
min 0 |
CAPTCHA2_RETRY_DELAY |
TWOCAPTCHA_TIMEOUTTimeout for CAPTCHA solving in seconds |
60 |
integer
min 5 |
CAPTCHA2_TIMEOUT fallback: TIMEOUT |
TWOCAPTCHA_AUTO_SUBMITAutomatically submit forms after CAPTCHA is solved |
false |
boolean
|
— |
Modal Closer
modalcloser
Automatically dismiss dialogs, cookie banners, and framework modals while the page is being archived.
#15
Snapshot
Modal Closer
modalcloserAutomatically dismiss dialogs, cookie banners, and framework modals while the page is being archived.
#15
Snapshot
Automatically dismiss dialogs, cookie banners, and framework modals while the page is being archived.
GitHubabx-dl --plugins=modalcloser 'https://example.com'MODALCLOSER_ENABLED=true archivebox add 'https://example.com'
order 15
background (daemon)
Snapshot
None
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
MODALCLOSER_ENABLEDEnable automatic modal and dialog closing |
true |
boolean
|
CLOSE_MODALS, AUTO_CLOSE_MODALS |
MODALCLOSER_TIMEOUTDelay before auto-closing dialogs (ms) |
1250 |
integer
min 100 |
— |
MODALCLOSER_POLL_INTERVALHow often to check for CSS modals (ms) |
500 |
integer
min 100 |
— |
Console Log
consolelog
Capture browser console messages emitted while the page loads.
#21
Snapshot
application/x-ndjson
Console Log
consolelogCapture browser console messages emitted while the page loads.
#21
Snapshot
application/x-ndjson
Capture browser console messages emitted while the page loads.
GitHubabx-dl --plugins=consolelog 'https://example.com'CONSOLELOG_ENABLED=true archivebox add 'https://example.com'
order 21
background (daemon)
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
CONSOLELOG_ENABLEDEnable console log capture |
true |
boolean
|
SAVE_CONSOLELOG, USE_CONSOLELOG |
CONSOLELOG_TIMEOUTTimeout for console log capture in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
DNS
dns
Record DNS activity observed while loading the page in Chrome.
#22
Snapshot
application/x-ndjson
DNS
dnsRecord DNS activity observed while loading the page in Chrome.
#22
Snapshot
application/x-ndjson
Record DNS activity observed while loading the page in Chrome.
GitHubabx-dl --plugins=dns 'https://example.com'DNS_ENABLED=true archivebox add 'https://example.com'
order 22
background (daemon)
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
DNS_ENABLEDEnable DNS traffic recording during page load |
true |
boolean
|
SAVE_DNS, USE_DNS |
DNS_TIMEOUTTimeout for DNS recording in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
SSL Certificates
sslcerts
Capture TLS certificate and connection metadata for the loaded page.
#23
Snapshot
application/x-ndjson
SSL Certificates
sslcertsCapture TLS certificate and connection metadata for the loaded page.
#23
Snapshot
application/x-ndjson
Capture TLS certificate and connection metadata for the loaded page.
GitHubabx-dl --plugins=sslcerts 'https://example.com'SSLCERTS_ENABLED=true archivebox add 'https://example.com'
order 23
background (daemon)
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
SSLCERTS_ENABLEDEnable SSL certificate capture |
true |
boolean
|
SAVE_SSLCERTS, USE_SSLCERTS |
SSLCERTS_TIMEOUTTimeout for SSL capture in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Responses
responses
Capture HTTP response metadata for requests made during page load.
#24
Snapshot
application/x-ndjson
text
image
audio
+3 more
Responses
responsesCapture HTTP response metadata for requests made during page load.
#24
Snapshot
application/x-ndjson
text
image
audio
+3 more
Capture HTTP response metadata for requests made during page load.
GitHubabx-dl --plugins=responses 'https://example.com'RESPONSES_ENABLED=true archivebox add 'https://example.com'
order 24
background (daemon)
Snapshot
application/x-ndjson
text
image
audio
video
application
font
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
RESPONSES_ENABLEDEnable HTTP response capture |
true |
boolean
|
SAVE_RESPONSES, USE_RESPONSES |
RESPONSES_TIMEOUTTimeout for response capture in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Redirects
redirects
Capture the redirect chain encountered while loading the page.
#25
Snapshot
application/x-ndjson
Redirects
redirectsCapture the redirect chain encountered while loading the page.
#25
Snapshot
application/x-ndjson
Capture the redirect chain encountered while loading the page.
GitHubabx-dl --plugins=redirects 'https://example.com'REDIRECTS_ENABLED=true archivebox add 'https://example.com'
order 25
background (daemon)
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
REDIRECTS_ENABLEDEnable redirect chain capture |
true |
boolean
|
SAVE_REDIRECTS, USE_REDIRECTS |
REDIRECTS_TIMEOUTTimeout for redirect capture in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Static File
staticfile
Download static-file responses when a URL resolves to a non-HTML asset (e.g. direct PDF, image, mp4, etc. URLs).
#26
Snapshot
Embed
application/pdf
application/epub+zip
image
audio
+8 more
Static File
staticfileDownload static-file responses when a URL resolves to a non-HTML asset (e.g. direct PDF, image, mp4, etc. URLs).
#26
Snapshot
Embed
application/pdf
application/epub+zip
image
audio
+8 more
Download static-file responses when a URL resolves to a non-HTML asset (e.g. direct PDF, image, mp4, etc. URLs).
GitHubabx-dl --plugins=staticfile 'https://example.com'STATICFILE_ENABLED=true archivebox add 'https://example.com'
order 26
background (daemon)
Snapshot
application/pdf
application/epub+zip
image
audio
video
application/json
application/xml
text/csv
text/xml
application/zip
application/octet-stream
application/x-
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
STATICFILE_ENABLEDEnable static file detection |
true |
boolean
|
SAVE_STATICFILE, USE_STATICFILE |
STATICFILE_TIMEOUTTimeout for static file detection in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Headers
headers
Capture HTTP headers for the main document response.
#27
Snapshot
application/json
Headers
headersCapture HTTP headers for the main document response.
#27
Snapshot
application/json
Capture HTTP headers for the main document response.
GitHubabx-dl --plugins=headers 'https://example.com'HEADERS_ENABLED=true archivebox add 'https://example.com'
order 27
background (daemon)
Snapshot
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
HEADERS_ENABLEDEnable HTTP headers capture |
true |
boolean
|
SAVE_HEADERS, USE_HEADERS |
HEADERS_TIMEOUTTimeout for headers capture in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Chrome
chrome
Needed by many other plugins to save high-fidelity archives within a real browser (does not save anything itself).
#30
Snapshot
node>=22.12.0 (env,node,apt,brew)
abxbus>=2.5.57 (pnpm)
+2 more
text/plain
application/json
Chrome
chromeNeeded by many other plugins to save high-fidelity archives within a real browser (does not save anything itself).
#30
Snapshot
node>=22.12.0 (env,node,apt,brew)
abxbus>=2.5.57 (pnpm)
+2 more
text/plain
application/json
Needed by many other plugins to save high-fidelity archives within a real browser (does not save anything itself).
GitHubabx-dl --plugins=chrome 'https://example.com'CHROME_ENABLED=true archivebox add 'https://example.com'
node
providers=env,node,apt,brew
min_version=22.12.0
abxbus
providers=pnpm
min_version=2.5.57
browsers
providers=pnpm
chromium
providers=env,playwright,puppeteer
min_version=149.0.0
order 89
foreground
CrawlSetup
order 90
background (daemon)
CrawlSetup
order 91
foreground
CrawlSetup
order 00
background (daemon)
Snapshot
order 01
background (daemon)
Snapshot
order 30
foreground
Snapshot
text/plain
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
AUTH_STORAGE_FILEPath to a persona auth.json cookie export; preserves full browser cookie attributes and takes precedence over COOKIES_FILE |
"" |
string
|
— |
COOKIES_FILEPath to a Netscape cookies.txt file to import before navigation |
"" |
string
|
— |
CHROME_ENABLEDEnable Chrome browser integration for archiving |
true |
boolean
|
USE_CHROME |
CHROME_BINARYPath to a Chromium-family browser binary |
"chromium" |
string
|
— |
CHROMEWEBSTORE_EXTENSIONS_DIRabxpkg-managed Chrome Web Store extension download/cache directory. This is intentionally not derived from PERSONAS_DIR/ACTIVE_PERSONA like runtime Chrome profile paths; Chrome reads unpacked extension artifacts from here while running with persona-derived user data dirs. |
"" |
string
|
— |
NODE_BINARYPath to Node.js binary |
"node" |
string
|
— |
CHROME_TIMEOUTTimeout for Chrome operations in seconds |
60 |
integer
min 5 |
fallback: TIMEOUT |
CHROME_HEADLESSRun Chrome in headless mode |
true |
boolean
|
— |
PERSONAS_DIRShared Chrome/browser personas root |
"" |
string
|
— |
ACTIVE_PERSONAActive browser persona name |
"Default" |
string
|
— |
CHROME_SANDBOXEnable Chrome sandbox (disable in Docker with --no-sandbox) |
true |
boolean
|
— |
CHROME_RESOLUTIONBrowser viewport resolution (width,height) |
"1440,2000" |
string
pattern ^\d+,\d+$ |
fallback: RESOLUTION |
CHROME_USER_AGENTUser agent string for Chrome |
"" |
string
|
fallback: USER_AGENT |
CHROME_CDP_URLConnect to an already-running browser over CDP instead of launching a new local Chrome process |
"" |
string
|
— |
CHROME_IS_LOCALWhether the managed browser process is local and should have a live chrome.pid marker |
true |
boolean
|
— |
CHROME_KEEPALIVEKeep the browser alive after the owning crawl/snapshot hook exits instead of closing it during cleanup |
false |
boolean
|
— |
CHROME_ISOLATIONWhether Chrome runs as one shared browser per crawl or a separate browser per snapshot |
"crawl" |
string
crawl | snapshot |
— |
CHROME_ARGSDefault Chrome command-line arguments (static flags only, dynamic args like --user-data-dir are added at runtime) |
[ "--no-first-run" "--no-default-browser-check" "--disable-default-apps" "--disable-sync" "--disable-infobars" "--disable-blink-features=AutomationControlled" "--disable-component-update" "--disable-domain-reliability" "--disable-breakpad" "--disable-client-side-phishing-detection" "--disable-hang-monitor" "--disable-speech-synthesis-api" "--disable-speech-api" "--disable-print-preview" "--disable-notifications" "--disable-desktop-notifications" "--disable-popup-blocking" "--disable-prompt-on-repost" "--disable-external-intent-requests" "--disable-session-crashed-bubble" "--disable-search-engine-choice-screen" "--disable-datasaver-prompt" "--ash-no-nudges" "--hide-crash-restore-bubble" "--suppress-message-center-popups" "--noerrdialogs" "--no-pings" "--silent-debugger-extension-api" "--deny-permission-prompts" "--enable-unsafe-extension-debugging" "--remote-allow-origins=*" "--safebrowsing-disable-auto-update" "--metrics-recording-only" "--password-store=basic" "--use-mock-keychain" "--disable-cookie-encryption" "--font-render-hinting=none" "--force-color-profile=srgb" "--disable-partial-raster" "--disable-skia-runtime-opts" "--disable-2d-canvas-clip-aa" "--enable-webgl" "--hide-scrollbars" "--export-tagged-pdf" "--generate-pdf-document-outline" "--disable-lazy-loading" "--disable-renderer-backgrounding" "--disable-background-networking" "--disable-background-timer-throttling" "--disable-backgrounding-occluded-windows" "--disable-ipc-flooding-protection" "--disable-extensions-http-throttling" "--disable-back-forward-cache" "--autoplay-policy=no-user-gesture-required" "--disable-gesture-requirement-for-media-playback" "--lang=en-US,en;q=0.9" "--log-level=2" "--enable-logging=stderr" |
array
|
CHROME_DEFAULT_ARGS |
CHROME_ARGS_EXTRAExtra arguments to append to Chrome command (for user customization) |
[] |
array
|
CHROME_EXTRA_ARGS |
CHROME_PAGELOAD_TIMEOUTTimeout for page navigation/load in seconds |
60 |
integer
min 5 |
fallback: CHROME_TIMEOUT |
CHROME_WAIT_FORPage load completion condition (domcontentloaded, load, networkidle0, networkidle2) |
"domcontentloaded" |
string
domcontentloaded | load | networkidle0 | networkidle2 |
— |
CHROME_DELAY_AFTER_LOADExtra delay in seconds after page load completes before archiving (useful for JS-heavy SPAs) |
0 |
number
min 0 |
— |
CHROME_CHECK_SSL_VALIDITYWhether to verify SSL certificates (disable for self-signed certs) |
true |
boolean
|
fallback: CHECK_SSL_VALIDITY |
yt-dlp
ytdlp
Download video and audio media with metadata, subtitles, thumbnails, and description sidecars.
#31
Snapshot
Embed
Fullscreen
yt-dlp (env,uv,apt,brew)
node (env,node,apt,brew)
+1 more
audio
video
image
application/x-subrip
+3 more
yt-dlp
ytdlpDownload video and audio media with metadata, subtitles, thumbnails, and description sidecars.
#31
Snapshot
Embed
Fullscreen
yt-dlp (env,uv,apt,brew)
node (env,node,apt,brew)
+1 more
audio
video
image
application/x-subrip
+3 more
Download video and audio media with metadata, subtitles, thumbnails, and description sidecars.
GitHubabx-dl --plugins=ytdlp 'https://example.com'YTDLP_ENABLED=true archivebox add 'https://example.com'
yt-dlp
providers=env,uv,apt,brew
node
providers=env,node,apt,brew
ffmpeg
providers=env,apt,brew
order 31
background (finite)
Snapshot
audio
video
image
application/x-subrip
text/vtt
application/json
text/plain
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
YTDLP_ENABLEDEnable video/audio downloading with yt-dlp |
true |
boolean
|
MEDIA_ENABLED, SAVE_MEDIA, USE_MEDIA, USE_YTDLP, FETCH_MEDIA, SAVE_YTDLP |
YTDLP_BINARYPath to yt-dlp binary |
"yt-dlp" |
string
|
YOUTUBEDL_BINARY, YOUTUBE_DL_BINARY |
NODE_BINARYPath to Node.js binary for yt-dlp JS runtime |
"node" |
string
|
— |
FFMPEG_BINARYPath to ffmpeg binary for yt-dlp media remuxing and downloads |
"ffmpeg" |
string
|
— |
YTDLP_TIMEOUTTimeout for yt-dlp downloads in seconds |
120 |
integer
min 10 |
MEDIA_TIMEOUT fallback: TIMEOUT |
YTDLP_COOKIES_FILEPath to cookies file |
"" |
string
|
fallback: COOKIES_FILE |
YTDLP_MAX_SIZEMaximum file size for yt-dlp downloads |
"750m" |
string
pattern ^\d+[kmgKMG]?$ |
MEDIA_MAX_SIZE |
YTDLP_CHECK_SSL_VALIDITYWhether to verify SSL certificates |
true |
boolean
|
fallback: CHECK_SSL_VALIDITY |
YTDLP_ARGSDefault yt-dlp arguments |
[ "--socket-timeout=5" "--retries=0" "--fragment-retries=0" "--extractor-retries=0" "--file-access-retries=0" "--restrict-filenames" "--trim-filenames=128" "--write-description" "--write-info-json" "--write-thumbnail" "--write-sub" "--write-auto-subs" "--convert-subs=srt" "--yes-playlist" "--continue" "--no-abort-on-error" "--ignore-errors" "--geo-bypass" "--add-metadata" "--no-progress" "--remote-components=ejs:github" "-o" "%(title)s.%(ext)s" |
array
|
YTDLP_DEFAULT_ARGS |
YTDLP_ARGS_EXTRAExtra arguments to append to yt-dlp command |
[] |
array
|
YTDLP_EXTRA_ARGS |
gallery-dl
gallerydl
Download image and media galleries along with metadata sidecars from supported sites.
#32
Snapshot
Embed
Fullscreen
gallery-dl (env,uv,apt,brew)
image
video
application/json
text/plain
+1 more
gallery-dl
gallerydlDownload image and media galleries along with metadata sidecars from supported sites.
#32
Snapshot
Embed
Fullscreen
gallery-dl (env,uv,apt,brew)
image
video
application/json
text/plain
+1 more
Download image and media galleries along with metadata sidecars from supported sites.
GitHubabx-dl --plugins=gallerydl 'https://example.com'GALLERYDL_ENABLED=true archivebox add 'https://example.com'gallery-dl
providers=env,uv,apt,brew
order 32
background (finite)
Snapshot
image
video
application/json
text/plain
application/zip
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
GALLERYDL_ENABLEDEnable gallery downloading with gallery-dl |
true |
boolean
|
SAVE_GALLERYDL, USE_GALLERYDL |
GALLERYDL_BINARYPath to gallery-dl binary |
"gallery-dl" |
string
|
— |
GALLERYDL_TIMEOUTTimeout for gallery downloads in seconds |
120 |
integer
min 10 |
fallback: TIMEOUT |
GALLERYDL_COOKIES_FILEPath to cookies file |
"" |
string
|
fallback: COOKIES_FILE |
GALLERYDL_CHECK_SSL_VALIDITYWhether to verify SSL certificates |
true |
boolean
|
fallback: CHECK_SSL_VALIDITY |
GALLERYDL_ARGSDefault gallery-dl arguments |
[ "--http-timeout=5" "--retries=0" "--write-metadata" "--write-info-json" |
array
|
GALLERYDL_DEFAULT_ARGS |
GALLERYDL_ARGS_EXTRAExtra arguments to append to gallery-dl command |
[] |
array
|
GALLERYDL_EXTRA_ARGS |
forum-dl
forumdl
Download forum threads and exports in JSONL, WARC, and mailbox-style archive formats.
#33
Snapshot
Embed
Fullscreen
forum-dl (env,uv)
application/x-ndjson
application/warc
message/rfc822
forum-dl
forumdlDownload forum threads and exports in JSONL, WARC, and mailbox-style archive formats.
#33
Snapshot
Embed
Fullscreen
forum-dl (env,uv)
application/x-ndjson
application/warc
message/rfc822
Download forum threads and exports in JSONL, WARC, and mailbox-style archive formats.
GitHubabx-dl --plugins=forumdl 'https://example.com'FORUMDL_ENABLED=true archivebox add 'https://example.com'forum-dl
providers=env,uv
order 33
background (finite)
Snapshot
application/x-ndjson
application/warc
message/rfc822
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
FORUMDL_ENABLEDEnable forum downloading with forum-dl |
true |
boolean
|
SAVE_FORUMDL, USE_FORUMDL |
FORUMDL_BINARYPath to forum-dl binary |
"forum-dl" |
string
|
— |
FORUMDL_TIMEOUTTimeout for forum downloads in seconds |
3600 |
integer
min 10 |
fallback: TIMEOUT |
FORUMDL_OUTPUT_FORMATOutput format for forum downloads |
"jsonl" |
string
jsonl | warc | mbox | maildir | mh | mmdf | babyl |
— |
FORUMDL_ARGSDefault forum-dl arguments. Keep autodetection deterministic by disabling forum-dl's retry loop unless explicitly overridden. |
[ "--timeout=5" "--retries=0" |
array
|
FORUMDL_DEFAULT_ARGS |
FORUMDL_ARGS_EXTRAExtra arguments to append to forum-dl command |
[] |
array
|
FORUMDL_EXTRA_ARGS |
Git
git
Clone git repositories from supported repository URLs into the snapshot output directory.
#34
Snapshot
Embed
git (env,apt,brew)
text
application
image
audio
+2 more
Git
gitClone git repositories from supported repository URLs into the snapshot output directory.
#34
Snapshot
Embed
git (env,apt,brew)
text
application
image
audio
+2 more
Clone git repositories from supported repository URLs into the snapshot output directory.
GitHubabx-dl --plugins=git 'https://example.com'GIT_ENABLED=true archivebox add 'https://example.com'git
providers=env,apt,brew
order 34
background (finite)
Snapshot
text
application
image
audio
video
font
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
GIT_ENABLEDEnable git repository cloning |
true |
boolean
|
SAVE_GIT, USE_GIT |
GIT_BINARYPath to git binary |
"git" |
string
|
— |
GIT_TIMEOUTTimeout for git operations in seconds |
120 |
integer
min 10 |
fallback: TIMEOUT |
GIT_DOMAINSComma-separated list of domains to treat as git repositories |
"github.com,gitlab.com,bitbucket.org,gist.github.com,codeberg.org,gitea.com,git.sr.ht" |
string
|
— |
GIT_ARGSDefault git arguments |
[ "clone" "--depth=1" "--recursive" |
array
|
GIT_DEFAULT_ARGS |
GIT_ARGS_EXTRAExtra arguments to append to git command |
[] |
array
|
GIT_EXTRA_ARGS |
wget
wget
Archive pages and their requisites with wget, optionally writing WARC captures.
#35
Snapshot
Embed
wget (env,apt,brew)
text/html
application/warc
application/gzip
image
+5 more
wget
wgetArchive pages and their requisites with wget, optionally writing WARC captures.
#35
Snapshot
Embed
wget (env,apt,brew)
text/html
application/warc
application/gzip
image
+5 more
Archive pages and their requisites with wget, optionally writing WARC captures.
GitHubabx-dl --plugins=wget 'https://example.com'WGET_ENABLED=true archivebox add 'https://example.com'
wget
providers=env,apt,brew
order 35
background (finite)
Snapshot
text/html
application/warc
application/gzip
image
text/css
application/javascript
font
audio
video
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
WGET_ENABLEDEnable wget archiving |
true |
boolean
|
SAVE_WGET, USE_WGET |
WGET_WARC_ENABLEDSave WARC archive file |
true |
boolean
|
SAVE_WARC, WGET_SAVE_WARC |
WGET_BINARYPath to wget binary |
"wget" |
string
|
— |
WGET_TIMEOUTTimeout for wget in seconds |
60 |
integer
min 5 |
fallback: TIMEOUT |
WGET_USER_AGENTUser agent string for wget |
"" |
string
|
fallback: USER_AGENT |
WGET_COOKIES_FILEPath to cookies file |
"" |
string
|
fallback: COOKIES_FILE |
WGET_CHECK_SSL_VALIDITYWhether to verify SSL certificates |
true |
boolean
|
fallback: CHECK_SSL_VALIDITY |
WGET_ARGSDefault wget arguments |
[ "--no-verbose" "--adjust-extension" "--convert-links" "--force-directories" "--backup-converted" "--span-hosts" "--no-parent" "--page-requisites" "--restrict-file-names=windows" "--tries=2" "-e" "robots=off" |
array
|
WGET_DEFAULT_ARGS |
WGET_ARGS_EXTRAExtra arguments to append to wget command |
[] |
array
|
WGET_EXTRA_ARGS |
Archive.org
archivedotorg
Submit URLs to the Internet Archive Wayback Machine and save the resulting archive link.
#36
Snapshot
Embed
text/plain
Archive.org
archivedotorgSubmit URLs to the Internet Archive Wayback Machine and save the resulting archive link.
#36
Snapshot
Embed
text/plain
Submit URLs to the Internet Archive Wayback Machine and save the resulting archive link.
GitHubabx-dl --plugins=archivedotorg 'https://example.com'ARCHIVEDOTORG_ENABLED=true archivebox add 'https://example.com'None
order 36
background (finite)
Snapshot
text/plain
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
ARCHIVEDOTORG_ENABLEDSubmit URLs to archive.org Wayback Machine |
true |
boolean
|
SAVE_ARCHIVEDOTORG, USE_ARCHIVEDOTORG, SUBMIT_ARCHIVEDOTORG |
ARCHIVEDOTORG_TIMEOUTTimeout for archive.org submission in seconds |
60 |
integer
min 10 |
fallback: TIMEOUT |
Favicon
favicon
Fetch and save the site favicon or touch icon.
#37
Snapshot
Embed
image
image/x-icon
Favicon
faviconFetch and save the site favicon or touch icon.
#37
Snapshot
Embed
image
image/x-icon
Fetch and save the site favicon or touch icon.
GitHubabx-dl --plugins=favicon 'https://example.com'FAVICON_ENABLED=true archivebox add 'https://example.com'None
order 37
background (finite)
Snapshot
image
image/x-icon
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
FAVICON_ENABLEDEnable favicon downloading |
true |
boolean
|
SAVE_FAVICON, USE_FAVICON |
FAVICON_TIMEOUTTimeout for favicon fetch in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
FAVICON_PROVIDERFallback favicon provider when not found via chrome tab. {} will be replaced with the domain. |
"https://www.google.com/s2/favicons?domain={}&format=ico" |
string
|
— |
SEO
seo
Capture SEO-related metadata such as meta tags and Open Graph fields.
#38
Snapshot
application/json
SEO
seoCapture SEO-related metadata such as meta tags and Open Graph fields.
#38
Snapshot
application/json
Capture SEO-related metadata such as meta tags and Open Graph fields.
GitHubabx-dl --plugins=seo 'https://example.com'SEO_ENABLED=true archivebox add 'https://example.com'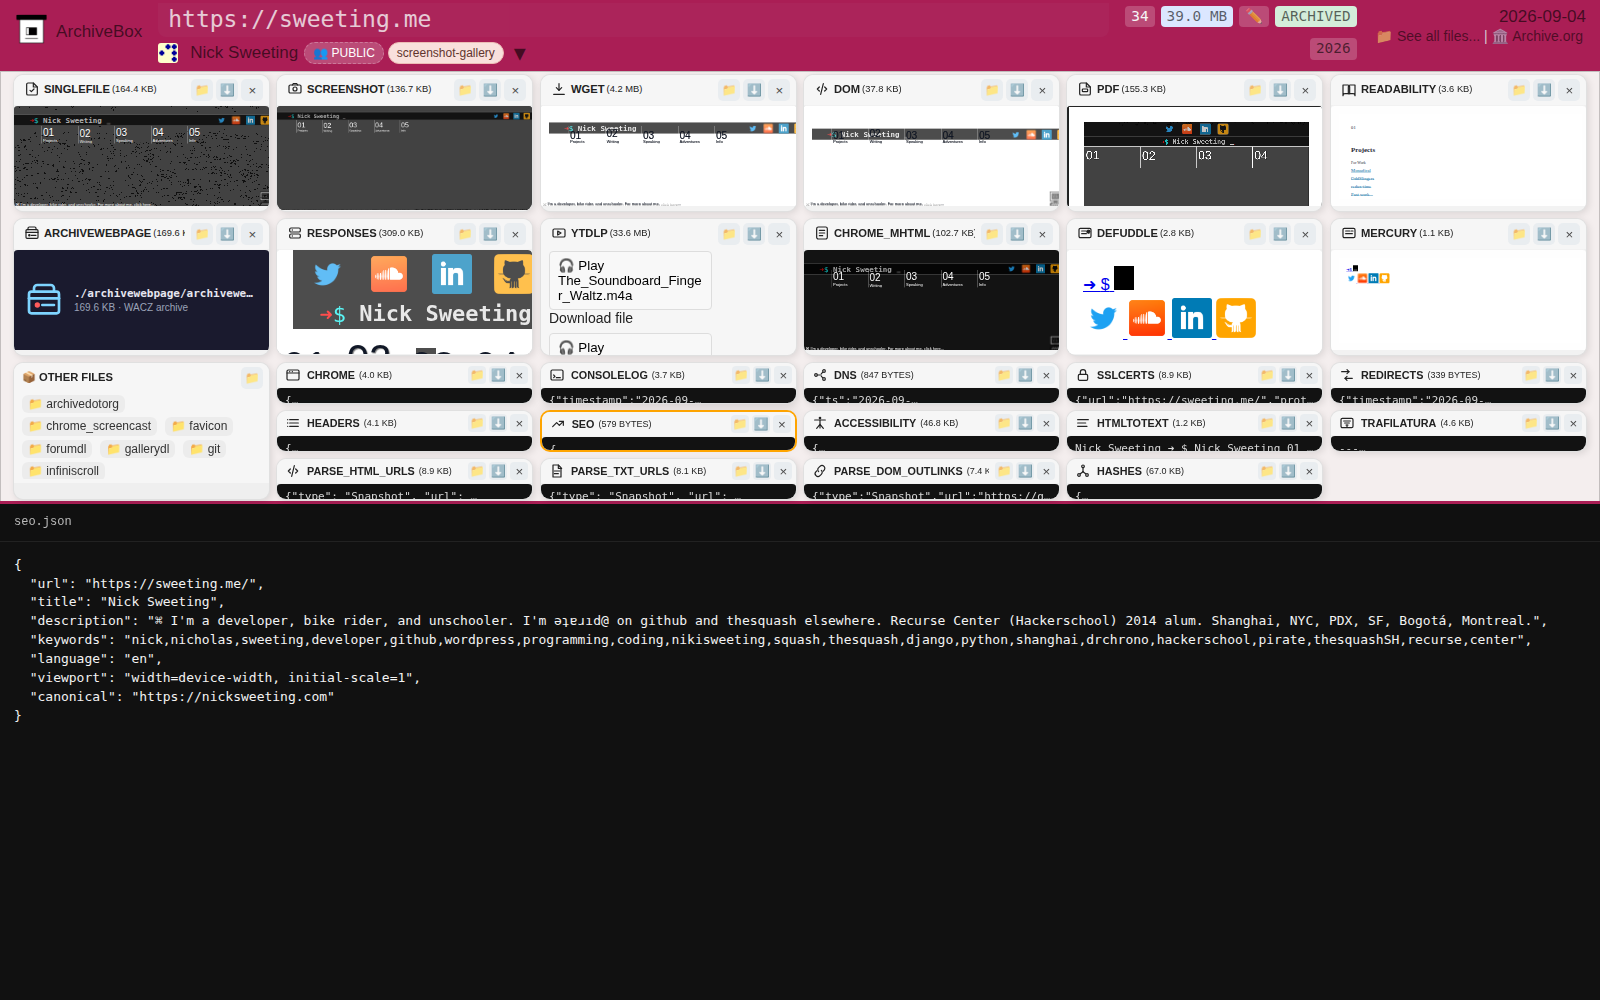
order 38
foreground
Snapshot
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
SEO_ENABLEDEnable SEO metadata capture |
true |
boolean
|
SAVE_SEO, USE_SEO |
SEO_TIMEOUTTimeout for SEO capture in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Accessibility
accessibility
Capture the browser accessibility tree for the archived page.
#39
Snapshot
application/json
Accessibility
accessibilityCapture the browser accessibility tree for the archived page.
#39
Snapshot
application/json
Capture the browser accessibility tree for the archived page.
GitHubabx-dl --plugins=accessibility 'https://example.com'ACCESSIBILITY_ENABLED=true archivebox add 'https://example.com'
order 39
foreground
Snapshot
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
ACCESSIBILITY_ENABLEDEnable accessibility tree capture |
true |
boolean
|
SAVE_ACCESSIBILITY, USE_ACCESSIBILITY |
ACCESSIBILITY_TIMEOUTTimeout for accessibility capture in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Infinite Scroll
infiniscroll
Expand infinite-scroll pages and load additional content before downstream capture plugins run.
#45
Snapshot
Infinite Scroll
infiniscrollExpand infinite-scroll pages and load additional content before downstream capture plugins run.
#45
Snapshot
Expand infinite-scroll pages and load additional content before downstream capture plugins run.
GitHubabx-dl --plugins=infiniscroll 'https://example.com'INFINISCROLL_ENABLED=true archivebox add 'https://example.com'
order 45
foreground
Snapshot
None
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
INFINISCROLL_ENABLEDEnable infinite scroll page expansion |
true |
boolean
|
SAVE_INFINISCROLL, USE_INFINISCROLL |
INFINISCROLL_TIMEOUTMaximum timeout for scrolling in seconds |
120 |
integer
min 10 |
— |
INFINISCROLL_SCROLL_DELAYDelay between scrolls in milliseconds |
2000 |
integer
min 500 |
— |
INFINISCROLL_SCROLL_DISTANCEDistance to scroll per step in pixels |
1600 |
integer
min 100 |
— |
INFINISCROLL_SCROLL_LIMITMaximum number of scroll steps |
10 |
integer
min 1 |
— |
INFINISCROLL_MIN_HEIGHTMinimum page height to scroll to in pixels |
16000 |
integer
min 1000 |
— |
INFINISCROLL_EXPAND_DETAILSExpand <details> elements and click 'load more' buttons for comments |
true |
boolean
|
— |
Claude Chrome
claudechrome
Use Claude computer-use to interact with pages in Chrome via CDP screenshots and the Anthropic API.
#47
Snapshot
Embed
Fullscreen
claudechrome (env,chromewebstore)
application/json
image/png
Claude Chrome
claudechromeUse Claude computer-use to interact with pages in Chrome via CDP screenshots and the Anthropic API.
#47
Snapshot
Embed
Fullscreen
claudechrome (env,chromewebstore)
application/json
image/png
Use Claude computer-use to interact with pages in Chrome via CDP screenshots and the Anthropic API.
GitHubabx-dl --plugins=claudechrome 'https://example.com'CLAUDECHROME_ENABLED=true archivebox add 'https://example.com'claudechrome
providers=env,chromewebstore
order 80
foreground
CrawlSetup
order 96
foreground
CrawlSetup
order 47
foreground
Snapshot
application/json
image/png
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
CLAUDECHROME_ENABLEDEnable Claude for Chrome browser extension for AI-driven page interaction |
false |
boolean
|
USE_CLAUDECHROME |
CLAUDECHROME_PROMPTPrompt for Claude to execute on the page. Claude can click buttons, fill forms, download files, and interact with any page element. |
"Look at the current page. If there are any "expand", "show more", "load more", or similar buttons/links, click them all to reveal hidden content. Report what you did." |
string
|
— |
CLAUDECHROME_TIMEOUTTimeout for Claude for Chrome operations in seconds |
120 |
integer
min 10 |
fallback: TIMEOUT |
CLAUDECHROME_MODELClaude model to use (e.g. claude-sonnet-4-6, claude-opus-4-6, claude-haiku-4-5-20251001). Availability depends on your plan. |
"claude-sonnet-4-6" |
string
|
— |
CLAUDECHROME_MAX_ACTIONSMaximum number of agentic loop iterations (screenshots + actions) per page |
15 |
integer
min 1 |
— |
ANTHROPIC_API_KEYAnthropic API key for Claude for Chrome authentication |
"" |
string
|
— |
SingleFile
singlefile
Save a complete page as a single self-contained HTML file using the SingleFile Chrome extension.
#50
Snapshot
Embed
singlefile (env,chromewebstore)
text/html
SingleFile
singlefileSave a complete page as a single self-contained HTML file using the SingleFile Chrome extension.
#50
Snapshot
Embed
singlefile (env,chromewebstore)
text/html
Save a complete page as a single self-contained HTML file using the SingleFile Chrome extension.
GitHubabx-dl --plugins=singlefile 'https://example.com'SINGLEFILE_ENABLED=true archivebox add 'https://example.com'
singlefile
providers=env,chromewebstore
order 80
foreground
CrawlSetup
order 50
foreground
Snapshot
text/html
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
SINGLEFILE_ENABLEDEnable SingleFile archiving |
true |
boolean
|
SAVE_SINGLEFILE, USE_SINGLEFILE |
SINGLEFILE_TIMEOUTTimeout for SingleFile in seconds |
60 |
integer
min 10 |
fallback: TIMEOUT |
Screenshot
screenshot
Capture a PNG screenshot of the rendered page.
#51
Snapshot
Embed
Fullscreen
image/png
Screenshot
screenshotCapture a PNG screenshot of the rendered page.
#51
Snapshot
Embed
Fullscreen
image/png
Capture a PNG screenshot of the rendered page.
GitHubabx-dl --plugins=screenshot 'https://example.com'SCREENSHOT_ENABLED=true archivebox add 'https://example.com'
order 51
foreground
Snapshot
image/png
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
SCREENSHOT_ENABLEDEnable screenshot capture |
true |
boolean
|
SAVE_SCREENSHOT, USE_SCREENSHOT |
SCREENSHOT_TIMEOUTTimeout for screenshot capture in seconds |
60 |
integer
min 5 |
fallback: TIMEOUT |
SCREENSHOT_WAIT_FOR_TEXTWait for text to appear in the page or one of its child frames before capture |
"" |
string
|
— |
SCREENSHOT_WAIT_FOR_FRAME_URLWhen waiting for text, only inspect frames whose URL contains this value |
"" |
string
|
— |
SCREENSHOT_RESOLUTIONScreenshot resolution (width,height) |
"1440,2000" |
string
pattern ^\d+,\d+$ |
fallback: RESOLUTION |
PDF
pdf
Render the current page to PDF using the shared Chrome session.
#52
Snapshot
Embed
Fullscreen
application/pdf
pdfRender the current page to PDF using the shared Chrome session.
#52
Snapshot
Embed
Fullscreen
application/pdf
Render the current page to PDF using the shared Chrome session.
GitHubabx-dl --plugins=pdf 'https://example.com'PDF_ENABLED=true archivebox add 'https://example.com'
order 52
foreground
Snapshot
application/pdf
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
PDF_ENABLEDEnable PDF generation |
true |
boolean
|
SAVE_PDF, USE_PDF |
PDF_TIMEOUTTimeout for PDF generation in seconds |
60 |
integer
min 5 |
fallback: TIMEOUT |
PDF_RESOLUTIONPDF page resolution (width,height) |
"1440,2000" |
string
pattern ^\d+,\d+$ |
fallback: RESOLUTION |
DOM
dom
Save the fully rendered DOM HTML from the live page.
#53
Snapshot
Embed
text/html
DOM
domSave the fully rendered DOM HTML from the live page.
#53
Snapshot
Embed
text/html
Save the fully rendered DOM HTML from the live page.
GitHubabx-dl --plugins=dom 'https://example.com'DOM_ENABLED=true archivebox add 'https://example.com'
order 53
foreground
Snapshot
text/html
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
DOM_ENABLEDEnable DOM capture |
true |
boolean
|
SAVE_DOM, USE_DOM |
DOM_TIMEOUTTimeout for DOM capture in seconds |
60 |
integer
min 5 |
fallback: TIMEOUT |
Chrome MHTML
chrome_mhtml
Save a browser-generated MHTML snapshot of the rendered page.
#54
Snapshot
Embed
Fullscreen
multipart/related
message/rfc822
Chrome MHTML
chrome_mhtmlSave a browser-generated MHTML snapshot of the rendered page.
#54
Snapshot
Embed
Fullscreen
multipart/related
message/rfc822
Save a browser-generated MHTML snapshot of the rendered page.
GitHubabx-dl --plugins=chrome_mhtml 'https://example.com'CHROME_MHTML_ENABLED=true archivebox add 'https://example.com'
order 54
foreground
Snapshot
multipart/related
message/rfc822
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
CHROME_MHTML_ENABLEDEnable browser-generated MHTML capture |
true |
boolean
|
SAVE_CHROME_MHTML, USE_CHROME_MHTML |
CHROME_MHTML_TIMEOUTTimeout for browser-generated MHTML capture in seconds |
60 |
integer
min 5 |
fallback: TIMEOUT |
Title
title
Capture the final document title from the rendered page.
#54
Snapshot
text/plain
Title
titleCapture the final document title from the rendered page.
#54
Snapshot
text/plain
Capture the final document title from the rendered page.
GitHubabx-dl --plugins=title 'https://example.com'TITLE_ENABLED=true archivebox add 'https://example.com'
order 54
foreground
Snapshot
text/plain
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
TITLE_ENABLEDEnable title extraction |
true |
boolean
|
SAVE_TITLE, USE_TITLE |
TITLE_TIMEOUTTimeout for title extraction in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Readability
readability
Extract article HTML, text, and metadata using Mozilla Readability.
#56
Snapshot
Embed
Fullscreen
readability-extractor (env,pnpm)
text/html
text/plain
application/json
Readability
readabilityExtract article HTML, text, and metadata using Mozilla Readability.
#56
Snapshot
Embed
Fullscreen
readability-extractor (env,pnpm)
text/html
text/plain
application/json
Extract article HTML, text, and metadata using Mozilla Readability.
GitHubabx-dl --plugins=readability 'https://example.com'READABILITY_ENABLED=true archivebox add 'https://example.com'
readability-extractor
providers=env,pnpm
order 56
foreground
Snapshot
text/html
text/plain
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
READABILITY_ENABLEDEnable Readability text extraction |
true |
boolean
|
SAVE_READABILITY, USE_READABILITY |
READABILITY_BINARYPath to readability-extractor binary |
"readability-extractor" |
string
|
— |
READABILITY_TIMEOUTTimeout for Readability in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
READABILITY_ARGSDefault Readability arguments |
[] |
array
|
READABILITY_DEFAULT_ARGS |
READABILITY_ARGS_EXTRAExtra arguments to append to Readability command |
[] |
array
|
READABILITY_EXTRA_ARGS |
Defuddle
defuddle
Extract cleaned article HTML, text, and metadata from archived HTML using Defuddle.
#57
Snapshot
defuddle (env,pnpm)
text/html
text/plain
application/json
Defuddle
defuddleExtract cleaned article HTML, text, and metadata from archived HTML using Defuddle.
#57
Snapshot
defuddle (env,pnpm)
text/html
text/plain
application/json
Extract cleaned article HTML, text, and metadata from archived HTML using Defuddle.
GitHubabx-dl --plugins=defuddle 'https://example.com'DEFUDDLE_ENABLED=true archivebox add 'https://example.com'
defuddle
providers=env,pnpm
order 57
foreground
Snapshot
text/html
text/plain
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
DEFUDDLE_ENABLEDEnable Defuddle text extraction |
true |
boolean
|
SAVE_DEFUDDLE, USE_DEFUDDLE |
DEFUDDLE_BINARYPath to defuddle binary |
"defuddle" |
string
|
— |
DEFUDDLE_TIMEOUTTimeout for Defuddle in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
DEFUDDLE_ARGSDefault Defuddle arguments |
[] |
array
|
DEFUDDLE_DEFAULT_ARGS |
DEFUDDLE_ARGS_EXTRAExtra arguments to append to Defuddle command |
[] |
array
|
DEFUDDLE_EXTRA_ARGS |
Mercury
mercury
Extract article HTML, text, and metadata using the Postlight Mercury parser.
#57
Snapshot
Embed
postlight-parser (env,npm)
text/html
text/plain
application/json
Mercury
mercuryExtract article HTML, text, and metadata using the Postlight Mercury parser.
#57
Snapshot
Embed
postlight-parser (env,npm)
text/html
text/plain
application/json
Extract article HTML, text, and metadata using the Postlight Mercury parser.
GitHubabx-dl --plugins=mercury 'https://example.com'MERCURY_ENABLED=true archivebox add 'https://example.com'
postlight-parser
providers=env,npm
order 57
foreground
Snapshot
text/html
text/plain
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
MERCURY_ENABLEDEnable Mercury text extraction |
true |
boolean
|
SAVE_MERCURY, USE_MERCURY |
MERCURY_BINARYPath to Mercury/Postlight parser binary |
"postlight-parser" |
string
|
— |
MERCURY_TIMEOUTTimeout for Mercury in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
MERCURY_ARGSDefault Mercury parser arguments |
[] |
array
|
MERCURY_DEFAULT_ARGS |
MERCURY_ARGS_EXTRAExtra arguments to append to Mercury parser command |
[] |
array
|
MERCURY_EXTRA_ARGS |
Claude Code Extract
claudecodeextract
Use Claude Code to generate clean Markdown from snapshot extractor outputs.
#58
Snapshot
Embed
Fullscreen
text/markdown
Claude Code Extract
claudecodeextractUse Claude Code to generate clean Markdown from snapshot extractor outputs.
#58
Snapshot
Embed
Fullscreen
text/markdown
Use Claude Code to generate clean Markdown from snapshot extractor outputs.
GitHubabx-dl --plugins=claudecodeextract 'https://example.com'CLAUDECODEEXTRACT_ENABLED=true archivebox add 'https://example.com'
order 58
foreground
Snapshot
text/markdown
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
CLAUDECODEEXTRACT_ENABLEDEnable Claude Code AI extraction |
false |
boolean
|
USE_CLAUDECODEEXTRACT |
CLAUDECODEEXTRACT_TIMEOUTTimeout for Claude Code extraction in seconds |
120 |
integer
min 10 |
fallback: CLAUDECODE_TIMEOUT |
CLAUDECODEEXTRACT_PROMPTCustom prompt for Claude Code extraction. Use this to define what Claude should extract or generate from the snapshot. |
"Create content.md in your output directory. Prefer readability/content.txt when it exists; otherwise read dom/output.html. Write clean Markdown for the archived page content. Stop after content.md has been written." |
string
|
— |
CLAUDECODEEXTRACT_MODELClaude model to use for extraction (e.g. claude-sonnet-4-6, claude-opus-4-6, claude-haiku-4-5-20251001) |
"claude-sonnet-4-6" |
string
|
fallback: CLAUDECODE_MODEL |
CLAUDECODEEXTRACT_MAX_TURNSMaximum number of agentic turns for extraction |
50 |
integer
min 1 |
fallback: CLAUDECODE_MAX_TURNS |
HTML to Text
htmltotext
Convert archived HTML from other extractors into plain text for indexing and analysis.
#58
Snapshot
text/plain
HTML to Text
htmltotextConvert archived HTML from other extractors into plain text for indexing and analysis.
#58
Snapshot
text/plain
Convert archived HTML from other extractors into plain text for indexing and analysis.
GitHubabx-dl --plugins=htmltotext 'https://example.com'HTMLTOTEXT_ENABLED=true archivebox add 'https://example.com'
None
order 58
foreground
Snapshot
text/plain
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
HTMLTOTEXT_ENABLEDEnable HTML to text conversion |
true |
boolean
|
SAVE_HTMLTOTEXT, USE_HTMLTOTEXT |
HTMLTOTEXT_TIMEOUTTimeout for HTML to text conversion in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
Trafilatura
trafilatura
Extract article content from archived HTML into text, markdown, HTML, CSV, JSON, and XML formats.
#59
Snapshot
trafilatura (uv,env)
text/plain
text/markdown
text/html
text/csv
+3 more
Trafilatura
trafilaturaExtract article content from archived HTML into text, markdown, HTML, CSV, JSON, and XML formats.
#59
Snapshot
trafilatura (uv,env)
text/plain
text/markdown
text/html
text/csv
+3 more
Extract article content from archived HTML into text, markdown, HTML, CSV, JSON, and XML formats.
GitHubabx-dl --plugins=trafilatura 'https://example.com'TRAFILATURA_ENABLED=true archivebox add 'https://example.com'
trafilatura
providers=uv,env
order 59
foreground
Snapshot
text/plain
text/markdown
text/html
text/csv
application/json
application/xml
application/tei+xml
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
TRAFILATURA_ENABLEDEnable Trafilatura extraction |
true |
boolean
|
SAVE_TRAFILATURA, USE_TRAFILATURA |
TRAFILATURA_BINARYPath to trafilatura binary |
"trafilatura" |
string
|
— |
TRAFILATURA_TIMEOUTTimeout for Trafilatura in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
TRAFILATURA_OUTPUT_FORMATSComma-separated trafilatura output formats to write (txt, markdown, html, csv, json, xml, xmltei) |
"txt,markdown,html" |
string
|
— |
OpenDataLoader
opendataloader
Extract structured text, tables, and metadata from PDFs using opendataloader-pdf. Supports OCR for scanned PDFs via hybrid backend.
#60
Snapshot
opendataloader-pdf (env,uv)
java>=11.0.0 (env,apt,brew)
text/plain
text/markdown
application/json
OpenDataLoader
opendataloaderExtract structured text, tables, and metadata from PDFs using opendataloader-pdf. Supports OCR for scanned PDFs via hybrid backend.
#60
Snapshot
opendataloader-pdf (env,uv)
java>=11.0.0 (env,apt,brew)
text/plain
text/markdown
application/json
Extract structured text, tables, and metadata from PDFs using opendataloader-pdf. Supports OCR for scanned PDFs via hybrid backend.
GitHubabx-dl --plugins=opendataloader 'https://example.com'OPENDATALOADER_ENABLED=true archivebox add 'https://example.com'opendataloader-pdf
providers=env,uv
java
providers=env,apt,brew
min_version=11.0.0
order 60
foreground
Snapshot
text/plain
text/markdown
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
OPENDATALOADER_ENABLEDEnable PDF text extraction with opendataloader-pdf |
false |
boolean
|
SAVE_OPENDATALOADER, USE_OPENDATALOADER |
OPENDATALOADER_BINARYPath to opendataloader-pdf binary |
"opendataloader-pdf" |
string
|
— |
OPENDATALOADER_JAVA_BINARYPath to the Java runtime used by opendataloader-pdf |
"java" |
string
|
fallback: JAVA_BINARY |
OPENDATALOADER_TIMEOUTTimeout for PDF extraction in seconds |
120 |
integer
min 10 |
fallback: TIMEOUT |
OPENDATALOADER_FORCE_OCRUse hybrid OCR backend (--hybrid docling-fast) for scanned/image-based PDFs. Requires opendataloader-pdf-hybrid server running. |
false |
boolean
|
— |
OPENDATALOADER_HYBRID_URLURL of the opendataloader-pdf-hybrid server (e.g. http://localhost:5002). If empty, uses the default built-in URL. |
"" |
string
|
— |
OPENDATALOADER_ARGSDefault opendataloader-pdf arguments |
[] |
array
|
OPENDATALOADER_DEFAULT_ARGS |
OPENDATALOADER_ARGS_EXTRAExtra arguments to append to opendataloader-pdf command |
[] |
array
|
OPENDATALOADER_EXTRA_ARGS |
LiteParse
liteparse
Extract text and metadata from PDFs, Office documents, and images using LiteParse (by LlamaIndex). Performs spatial PDF parsing via PDFium and optional OCR via Tesseract.
#61
Snapshot
lit>=2.0.0 (env,pnpm)
tesseract>=5.0.0 (env,apt,brew)
+1 more
text/plain
application/json
LiteParse
liteparseExtract text and metadata from PDFs, Office documents, and images using LiteParse (by LlamaIndex). Performs spatial PDF parsing via PDFium and optional OCR via Tesseract.
#61
Snapshot
lit>=2.0.0 (env,pnpm)
tesseract>=5.0.0 (env,apt,brew)
+1 more
text/plain
application/json
Extract text and metadata from PDFs, Office documents, and images using LiteParse (by LlamaIndex). Performs spatial PDF parsing via PDFium and optional OCR via Tesseract.
GitHubabx-dl --plugins=liteparse 'https://example.com'LITEPARSE_ENABLED=true archivebox add 'https://example.com'lit
providers=env,pnpm
min_version=2.0.0
tesseract
providers=env,apt,brew
min_version=5.0.0
convert
providers=env,apt,brew
min_version=6.0.0
order 61
foreground
Snapshot
text/plain
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
LITEPARSE_ENABLEDEnable LiteParse document extraction |
true |
boolean
|
SAVE_LITEPARSE, USE_LITEPARSE |
LITEPARSE_BINARYPath to lit binary |
"lit" |
string
|
— |
LITEPARSE_TESSERACT_BINARYPath to the tesseract binary used to discover the system tessdata directory. Auto-installed by the plugin via brew/apt; not invoked at runtime — lit's bundled tesseract-rs does the actual OCR. |
"tesseract" |
string
|
— |
LITEPARSE_IMAGEMAGICK_BINARYPath to an ImageMagick binary used by LiteParse for image conversion. Auto-installed by the plugin via brew/apt; not invoked directly by this hook. |
"convert" |
string
|
— |
LITEPARSE_TIMEOUTTimeout for LiteParse extraction in seconds |
180 |
integer
min 10 |
fallback: TIMEOUT |
LITEPARSE_FORMATSOutput formats to produce, one file per source. `text` writes `<input>.txt` (lit's plain layout-preserving text — what search backends index). `json` is also supported and writes `<input>.json` with lit v2's structured per-page output (text, bounding boxes, font metadata, OCR confidence); not indexed by search backends. Any subset of [text, json] is valid. |
[ "text" |
array
|
— |
LITEPARSE_OCR_ENABLEDRun Tesseract OCR on pages/images without embedded text (passes --no-ocr when disabled) |
true |
boolean
|
— |
LITEPARSE_OCR_LANGUAGETesseract OCR language code (e.g. eng, fra, deu, chi_sim) |
"eng" |
string
|
— |
LITEPARSE_OCR_SERVER_URLOptional HTTP OCR server URL (e.g. EasyOCR/PaddleOCR wrapper) to use instead of bundled Tesseract |
"" |
string
|
— |
LITEPARSE_TESSDATA_DIRPath to a Tesseract tessdata directory containing <lang>.traineddata files. Auto-detected from common system locations when empty. |
"" |
string
|
TESSDATA_PREFIX |
LITEPARSE_MAX_PAGESMaximum pages to parse per document |
1000 |
integer
min 1 |
— |
LITEPARSE_TARGET_PAGESPage range to parse, e.g. '1-5,10,15-20'. Empty means all pages. |
"" |
string
|
— |
LITEPARSE_DPIRendering DPI used when rasterising pages for OCR / images |
150 |
integer
min 50 |
— |
LITEPARSE_PASSWORDPassword for encrypted PDFs |
"" |
string
|
— |
LITEPARSE_MIN_IMAGE_DIMENSIONSkip image files (PNG/JPG/etc.) smaller than this many pixels in both width AND height. Avoids wasting OCR time on favicons, sprite thumbnails, and tracking pixels. Set to 0 to disable filtering. |
128 |
integer
min 0 |
— |
LITEPARSE_BATCH_SIZENumber of source documents processed per `lit batch-parse` invocation. Sources are sorted largest-first so the most content-rich files come back first. Smaller batches give finer-grained progressive output but slightly more lit-startup overhead. |
8 |
integer
min 1 |
— |
LITEPARSE_MAX_SOURCESHard cap on number of documents to process per snapshot, applied after size-desc sort so the largest files always make it. Set to 0 for no cap. |
100 |
integer
min 0 |
— |
LITEPARSE_PARALLEL_WORKERSNumber of concurrent `lit batch-parse` processes. Each process is pinned to --num-workers=1 internally (its own multi-worker mode hurts on Apple Silicon); outer parallelism via this knob gives near-linear speedup up to a few procs. Empirically 2 is enough to fit a typical content-heavy article under the 60s hook timeout. |
2 |
integer
min 1 |
— |
LITEPARSE_ARGSDefault LiteParse arguments |
[] |
array
|
LITEPARSE_DEFAULT_ARGS |
LITEPARSE_ARGS_EXTRAExtra arguments to append to LiteParse command |
[] |
array
|
LITEPARSE_EXTRA_ARGS |
ArchiveWeb.page
archivewebpage
Record a high-fidelity WACZ web archive of the page using the Webrecorder ArchiveWeb.page Chrome extension.
#65
Snapshot
Embed
Fullscreen
archivewebpage (env,chromewebstore)
application/wacz+zip
application/wacz
ArchiveWeb.page
archivewebpageRecord a high-fidelity WACZ web archive of the page using the Webrecorder ArchiveWeb.page Chrome extension.
#65
Snapshot
Embed
Fullscreen
archivewebpage (env,chromewebstore)
application/wacz+zip
application/wacz
Record a high-fidelity WACZ web archive of the page using the Webrecorder ArchiveWeb.page Chrome extension.
GitHubabx-dl --plugins=archivewebpage 'https://example.com'ARCHIVEWEBPAGE_ENABLED=true archivebox add 'https://example.com'
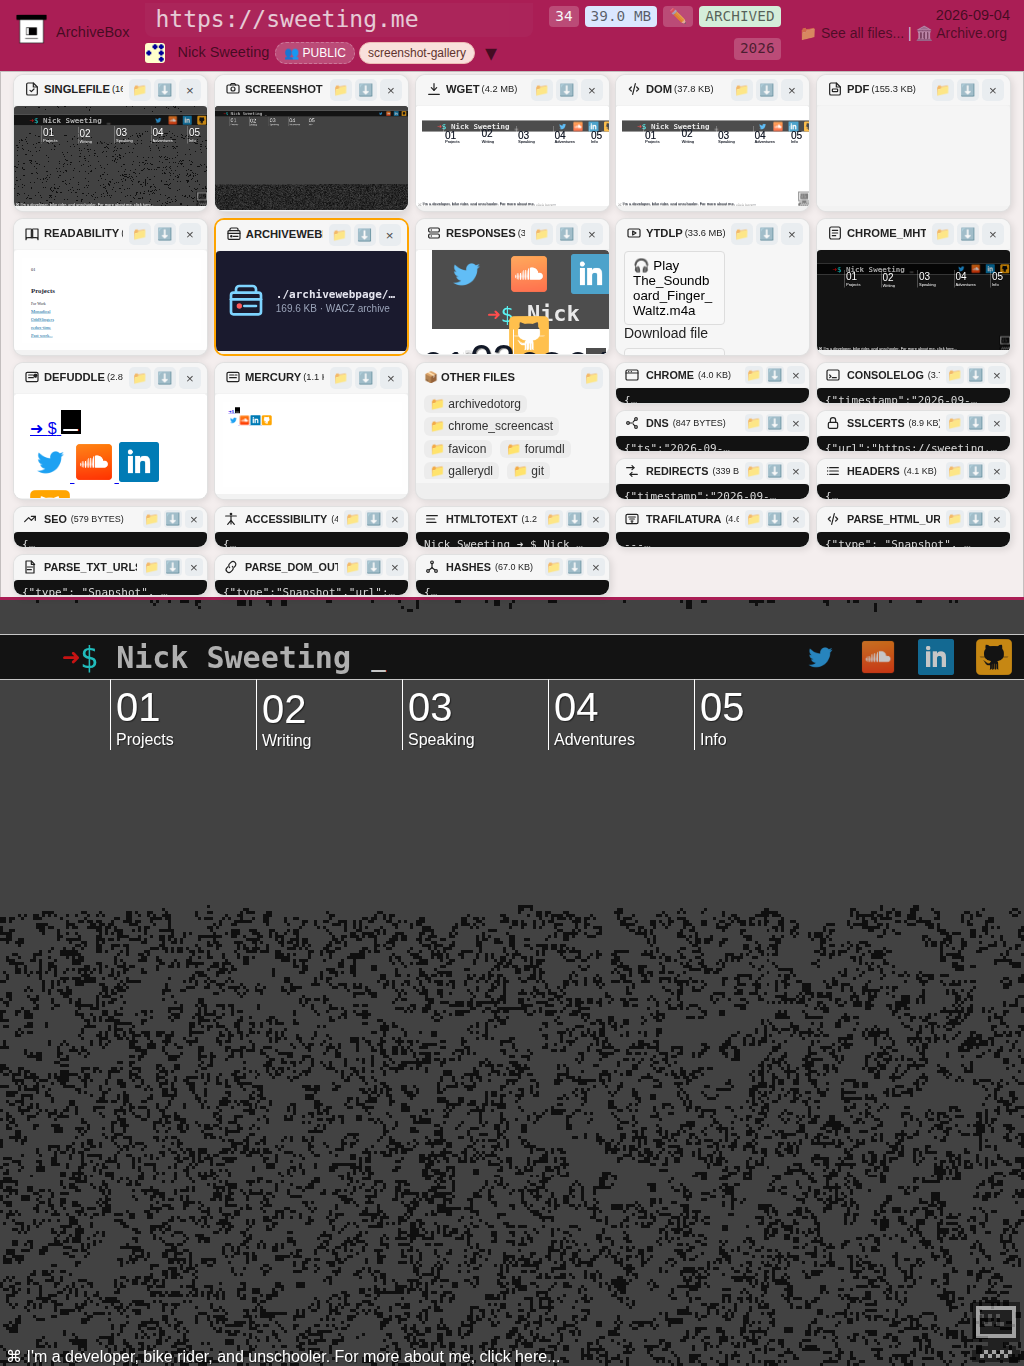
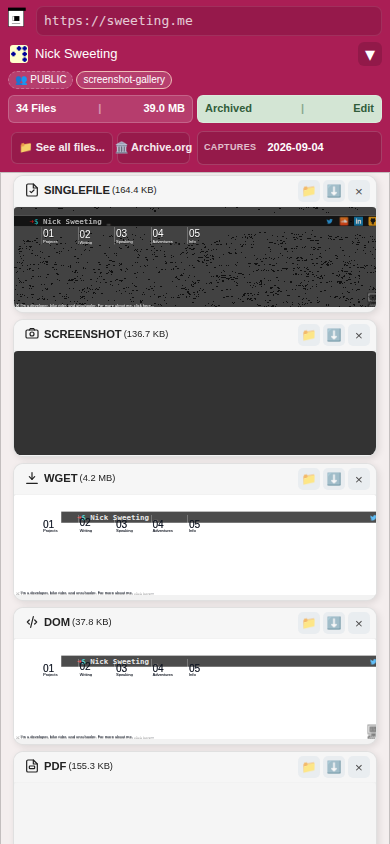
archivewebpage
providers=env,chromewebstore
order 80
foreground
CrawlSetup
order 16
foreground
Snapshot
order 65
foreground
Snapshot
application/wacz+zip
application/wacz
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
ARCHIVEWEBPAGE_ENABLEDEnable ArchiveWeb.page WACZ recording during archiving |
true |
boolean
|
USE_ARCHIVEWEBPAGE, SAVE_ARCHIVEWEBPAGE, SAVE_WACZ, USE_WACZ |
ARCHIVEWEBPAGE_TIMEOUTMaximum seconds to wait for the WACZ download after stopping recording |
60 |
integer
min 5 |
fallback: TIMEOUT |
ARCHIVEWEBPAGE_HOOK_BUDGET_MSSoft per-hook latency budget in ms (start/stop hooks try to finish within this; not a hard cutoff for large captures) |
2000 |
integer
min 250 |
— |
ARCHIVEWEBPAGE_AUTORUN_BEHAVIORSRun AWP behaviors (autopilot) during recording. Off by default since infiniscroll/other plugins drive page actions. |
false |
boolean
|
ARCHIVEWEBPAGE_AUTOPILOT |
ARCHIVEWEBPAGE_COLLECTION_TITLECollection title to use when AWP has no default collection yet |
"abx-dl" |
string
|
— |
papers-dl
papersdl
Fetch downloadable academic papers from paper URLs and DOI targets.
#66
Snapshot
Embed
Fullscreen
papers-dl (env,uv)
application/pdf
papers-dl
papersdlFetch downloadable academic papers from paper URLs and DOI targets.
#66
Snapshot
Embed
Fullscreen
papers-dl (env,uv)
application/pdf
Fetch downloadable academic papers from paper URLs and DOI targets.
GitHubabx-dl --plugins=papersdl 'https://example.com'PAPERSDL_ENABLED=true archivebox add 'https://example.com'papers-dl
providers=env,uv
order 66
background (finite)
Snapshot
application/pdf
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
PAPERSDL_ENABLEDEnable paper downloading with papers-dl |
true |
boolean
|
SAVE_PAPERSDL, USE_PAPERSDL |
PAPERSDL_BINARYPath to papers-dl binary |
"papers-dl" |
string
|
— |
PAPERSDL_TIMEOUTTimeout for paper downloads in seconds |
300 |
integer
min 10 |
fallback: TIMEOUT |
PAPERSDL_ARGSDefault papers-dl arguments |
[ "fetch" |
array
|
PAPERSDL_DEFAULT_ARGS |
PAPERSDL_ARGS_EXTRAExtra arguments to append to papers-dl command |
[] |
array
|
PAPERSDL_EXTRA_ARGS |
Parse HTML URLs
parse_html_urls
Parse HTML documents and emit discovered links as JSONL snapshot records.
#70
Snapshot
application/x-ndjson
Parse HTML URLs
parse_html_urlsParse HTML documents and emit discovered links as JSONL snapshot records.
#70
Snapshot
application/x-ndjson
Parse HTML documents and emit discovered links as JSONL snapshot records.
GitHubabx-dl --plugins=parse_html_urls 'https://example.com'PARSE_HTML_URLS_ENABLED=true archivebox add 'https://example.com'


None
order 70
foreground
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
PARSE_HTML_URLS_ENABLEDEnable HTML URL parsing |
true |
boolean
|
USE_PARSE_HTML_URLS |
Parse Text URLs
parse_txt_urls
Parse plain text documents and emit discovered URLs as JSONL snapshot records.
#71
Snapshot
application/x-ndjson
Parse Text URLs
parse_txt_urlsParse plain text documents and emit discovered URLs as JSONL snapshot records.
#71
Snapshot
application/x-ndjson
Parse plain text documents and emit discovered URLs as JSONL snapshot records.
GitHubabx-dl --plugins=parse_txt_urls 'https://example.com'PARSE_TXT_URLS_ENABLED=true archivebox add 'https://example.com'


None
order 71
foreground
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
PARSE_TXT_URLS_ENABLEDEnable plain text URL parsing |
true |
boolean
|
USE_PARSE_TXT_URLS |
Parse RSS URLs
parse_rss_urls
Parse RSS and Atom feeds and emit discovered entry URLs as JSONL snapshot records.
#72
Snapshot
feedparser (uv,env)
application/x-ndjson
Parse RSS URLs
parse_rss_urlsParse RSS and Atom feeds and emit discovered entry URLs as JSONL snapshot records.
#72
Snapshot
feedparser (uv,env)
application/x-ndjson
Parse RSS and Atom feeds and emit discovered entry URLs as JSONL snapshot records.
GitHubabx-dl --plugins=parse_rss_urls 'https://example.com'PARSE_RSS_URLS_ENABLED=true archivebox add 'https://example.com'feedparser
providers=uv,env
order 72
foreground
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
PARSE_RSS_URLS_ENABLEDEnable RSS/Atom feed URL parsing |
true |
boolean
|
USE_PARSE_RSS_URLS |
Parse Netscape URLs
parse_netscape_urls
Parse Netscape bookmark HTML exports and emit discovered URLs as JSONL snapshot records.
#73
Snapshot
application/x-ndjson
Parse Netscape URLs
parse_netscape_urlsParse Netscape bookmark HTML exports and emit discovered URLs as JSONL snapshot records.
#73
Snapshot
application/x-ndjson
Parse Netscape bookmark HTML exports and emit discovered URLs as JSONL snapshot records.
GitHubabx-dl --plugins=parse_netscape_urls 'https://example.com'PARSE_NETSCAPE_URLS_ENABLED=true archivebox add 'https://example.com'None
order 73
foreground
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
PARSE_NETSCAPE_URLS_ENABLEDEnable Netscape bookmarks HTML URL parsing |
true |
boolean
|
USE_PARSE_NETSCAPE_URLS |
Parse JSONL URLs
parse_jsonl_urls
Parse JSONL bookmark exports and emit discovered URLs as JSONL snapshot records.
#74
Snapshot
application/x-ndjson
Parse JSONL URLs
parse_jsonl_urlsParse JSONL bookmark exports and emit discovered URLs as JSONL snapshot records.
#74
Snapshot
application/x-ndjson
Parse JSONL bookmark exports and emit discovered URLs as JSONL snapshot records.
GitHubabx-dl --plugins=parse_jsonl_urls 'https://example.com'PARSE_JSONL_URLS_ENABLED=true archivebox add 'https://example.com'None
order 74
foreground
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
PARSE_JSONL_URLS_ENABLEDEnable JSON Lines URL parsing |
true |
boolean
|
USE_PARSE_JSONL_URLS |
Parse DOM Outlinks
parse_dom_outlinks
Extract crawlable links from the rendered DOM and emit them as JSONL records.
#75
Snapshot
application/x-ndjson
Parse DOM Outlinks
parse_dom_outlinksExtract crawlable links from the rendered DOM and emit them as JSONL records.
#75
Snapshot
application/x-ndjson
Extract crawlable links from the rendered DOM and emit them as JSONL records.
GitHubabx-dl --plugins=parse_dom_outlinks 'https://example.com'PARSE_DOM_OUTLINKS_ENABLED=true archivebox add 'https://example.com'


order 75
foreground
Snapshot
application/x-ndjson
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
PARSE_DOM_OUTLINKS_ENABLEDEnable DOM outlinks parsing from archived pages |
true |
boolean
|
SAVE_DOM_OUTLINKS, USE_PARSE_DOM_OUTLINKS |
PARSE_DOM_OUTLINKS_TIMEOUTTimeout for DOM outlinks parsing in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
SQLite Search
search_backend_sqlite
Index archived snapshot content into a SQLite FTS database for local search.
#90
Snapshot
application/vnd.sqlite3
SQLite Search
search_backend_sqliteIndex archived snapshot content into a SQLite FTS database for local search.
#90
Snapshot
application/vnd.sqlite3
Index archived snapshot content into a SQLite FTS database for local search.
GitHubabx-dl --plugins=search_backend_sqlite 'https://example.com'SEARCH_BACKEND_SQLITE_ENABLED=true archivebox add 'https://example.com'None
order 90
foreground
Snapshot
application/vnd.sqlite3
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
SEARCH_BACKEND_SQLITE_ENABLEDIndex archived snapshots into the SQLite FTS database. |
false |
boolean
|
— |
SEARCH_BACKEND_SQLITE_DBSQLite FTS database filename |
"search.sqlite3" |
string
|
SQLITEFTS_DB |
SEARCH_BACKEND_SQLITE_SEPARATE_DATABASEUse separate database file for FTS index |
true |
boolean
|
FTS_SEPARATE_DATABASE, SQLITEFTS_SEPARATE_DATABASE |
SEARCH_BACKEND_SQLITE_TOKENIZERSFTS5 tokenizer configuration |
"porter unicode61 remove_diacritics 2" |
string
|
FTS_TOKENIZERS, SQLITEFTS_TOKENIZERS |
Sonic Search
search_backend_sonic
Index archived snapshot content into a Sonic search backend.
#91
Snapshot
sonic (env,bash,apt,brew,cargo)
Sonic Search
search_backend_sonicIndex archived snapshot content into a Sonic search backend.
#91
Snapshot
sonic (env,bash,apt,brew,cargo)
Index archived snapshot content into a Sonic search backend.
GitHubabx-dl --plugins=search_backend_sonic 'https://example.com'SEARCH_BACKEND_SONIC_ENABLED=true archivebox add 'https://example.com'sonic
providers=env,bash,apt,brew,cargo
order 91
foreground
Snapshot
None
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
SEARCH_BACKEND_SONIC_ENABLEDIndex archived snapshots into the Sonic search backend. |
true |
boolean
|
— |
SONIC_BINARYPath to Sonic server binary |
"sonic" |
string
|
— |
SONIC_DIRDirectory used to store the Sonic config, logs, and index data |
"" |
string
|
— |
SEARCH_BACKEND_SONIC_HOST_NAMESonic server hostname |
"127.0.0.1" |
string
|
SEARCH_BACKEND_HOST_NAME, SONIC_HOST |
SEARCH_BACKEND_SONIC_PORTSonic server port |
1491 |
integer
min 1 |
SEARCH_BACKEND_PORT, SONIC_PORT |
SEARCH_BACKEND_SONIC_PASSWORDSonic server password |
"SecretPassword" |
string
|
SEARCH_BACKEND_PASSWORD, SONIC_PASSWORD |
SEARCH_BACKEND_SONIC_COLLECTIONSonic collection name |
"archivebox" |
string
|
SONIC_COLLECTION |
SEARCH_BACKEND_SONIC_BUCKETSonic bucket name |
"snapshots" |
string
|
SONIC_BUCKET |
Claude Code Cleanup
claudecodecleanup
Use Claude Code to deduplicate and clean up redundant snapshot extractor outputs.
#92
Snapshot
Embed
Fullscreen
text/plain
Claude Code Cleanup
claudecodecleanupUse Claude Code to deduplicate and clean up redundant snapshot extractor outputs.
#92
Snapshot
Embed
Fullscreen
text/plain
Use Claude Code to deduplicate and clean up redundant snapshot extractor outputs.
GitHubabx-dl --plugins=claudecodecleanup 'https://example.com'CLAUDECODECLEANUP_ENABLED=true archivebox add 'https://example.com'
order 92
foreground
Snapshot
text/plain
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
CLAUDECODECLEANUP_ENABLEDEnable Claude Code AI cleanup of snapshot files |
false |
boolean
|
USE_CLAUDECODECLEANUP |
CLAUDECODECLEANUP_TIMEOUTTimeout for Claude Code cleanup in seconds |
180 |
integer
min 10 |
fallback: CLAUDECODE_TIMEOUT |
CLAUDECODECLEANUP_PROMPTCustom prompt for Claude Code cleanup. Defines what Claude should clean up and how to determine which duplicates to keep. |
"Use the deterministic inventory supplied below; do not inventory the snapshot again. From that evidence, keep the best output in each redundant group and select deletion ids only for clearly inferior duplicates, incomplete or failed outputs, and empty directories; when uncertain, keep the output. Never request deletion of hashes/, claudecodecleanup/, JSON metadata, or ArchiveBox process-control files. Return a concise report naming every extractor directory considered, every requested deletion, and every retained duplicate group." |
string
|
— |
CLAUDECODECLEANUP_MODELClaude model to use for cleanup (e.g. claude-sonnet-4-6, claude-opus-4-6, claude-haiku-4-5-20251001) |
"claude-sonnet-4-6" |
string
|
fallback: CLAUDECODE_MODEL |
CLAUDECODECLEANUP_MAX_TURNSMaximum number of agentic turns for cleanup |
50 |
integer
min 1 |
fallback: CLAUDECODE_MAX_TURNS |
Hashes
hashes
Generate a hash manifest for files produced in the snapshot directory.
#93
Snapshot
application/json
Hashes
hashesGenerate a hash manifest for files produced in the snapshot directory.
#93
Snapshot
application/json
Generate a hash manifest for files produced in the snapshot directory.
GitHubabx-dl --plugins=hashes 'https://example.com'HASHES_ENABLED=true archivebox add 'https://example.com'


None
order 93
foreground
Snapshot
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
HASHES_ENABLEDEnable merkle tree hash generation |
true |
boolean
|
SAVE_HASHES, USE_HASHES |
HASHES_TIMEOUTTimeout for merkle tree generation in seconds |
30 |
integer
min 5 |
fallback: TIMEOUT |
TLSNotary
tlsnotary
Opt-in private TLSNotary browser-extension capture. Adds MPC computation, bandwidth and seconds or minutes to archiving. The public verifier sees destination hostname, sizes and timing, plus a fixed HTTP protocol marker, but receives no URL path/query, cookies or page content. A compact signed receipt authenticates the separately replayed main response saved by this plugin; other archive outputs are not automatically certified.
#95
Snapshot
Embed
Fullscreen
tlsnotary (env,chromewebstore)
application/vnd.archivebox.tlsnotary
text/html
application/json
TLSNotary
tlsnotaryOpt-in private TLSNotary browser-extension capture. Adds MPC computation, bandwidth and seconds or minutes to archiving. The public verifier sees destination hostname, sizes and timing, plus a fixed HTTP protocol marker, but receives no URL path/query, cookies or page content. A compact signed receipt authenticates the separately replayed main response saved by this plugin; other archive outputs are not automatically certified.
#95
Snapshot
Embed
Fullscreen
tlsnotary (env,chromewebstore)
application/vnd.archivebox.tlsnotary
text/html
application/json
Opt-in private TLSNotary browser-extension capture. Adds MPC computation, bandwidth and seconds or minutes to archiving. The public verifier sees destination hostname, sizes and timing, plus a fixed HTTP protocol marker, but receives no URL path/query, cookies or page content. A compact signed receipt authenticates the separately replayed main response saved by this plugin; other archive outputs are not automatically certified.
GitHubabx-dl --plugins=tlsnotary 'https://example.com'TLSNOTARY_ENABLED=true archivebox add 'https://example.com'tlsnotary
providers=env,chromewebstore
order 80
foreground
CrawlSetup
order 95
foreground
Snapshot
application/vnd.archivebox.tlsnotary
text/html
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
TLSNOTARY_ENABLEDEnable private extension proofs; significantly increases archiving time and bandwidth. |
false |
boolean
|
— |
TLSNOTARY_VERIFIER_URLVerifier and signed-receipt service. HTTP is permitted only for local development. |
"https://tlsnotary.zervice.io" |
string
|
— |
TLSNOTARY_TRUSTED_KEYIndependently trusted Ed25519 public key (base64 SPKI); empty uses the bundled service key. |
"" |
string
|
— |
TLSNOTARY_TIMEOUTHard per-capture deadline in seconds; no retries or effect on other plugins. |
180 |
integer
min 5 |
— |
TLSNOTARY_MAX_RECV_BYTESMaximum complete HTTP response bytes. Oversized pages fail explicitly; assets and video streams are excluded. |
131072 |
integer
min 1024 |
— |
TLSNOTARY_MAX_SENT_BYTESMaximum authenticated request bytes including Chrome cookies/headers. |
4096 |
integer
min 512 |
— |
Base
base
Provide shared utilities, helpers, and test support used by other plugins.
Base
baseProvide shared utilities, helpers, and test support used by other plugins.
Provide shared utilities, helpers, and test support used by other plugins.
GitHubabx-dl plugins basearchivebox add 'https://example.com'Utility plugins are typically consumed indirectly, so the example shows the closest inspection workflow.
None
No hook scripts.
None
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
ABX_RUNTIMECurrent host runtime name, eg. abx-dl or archivebox |
"abx-dl" |
string
|
— |
ABX_INSTALL_CACHERuntime-derived install preflight cache keyed by binary name |
{{}} |
object
|
— |
SNAP_DIRBase snapshot directory for per-snapshot hook output |
"" |
string
|
— |
CRAWL_DIRBase crawl directory for per-crawl hook output |
"" |
string
|
— |
DATA_DIRBase collection directory for shared crawl/index state |
"" |
string
|
— |
ABXPKG_LIB_DIRShared tools and binary installation root |
"" |
string
|
— |
PERSONAS_DIRShared personas root |
"" |
string
|
— |
ACTIVE_PERSONAActive browser persona name |
"Default" |
string
|
— |
EXTRA_CONTEXTOpaque correlation fields reflected unchanged into emitted JSONL records. Hooks must never inspect this object or use it as input; use CLI args or files for required data. |
"" |
string
|
— |
TIMEOUTDefault timeout in seconds for hooks that support a TIMEOUT fallback |
60 |
integer
min 0 |
— |
USER_AGENTDefault user agent string for HTTP requests and browser automation |
"Mozilla/5.0 (compatible; ArchiveBox/1.0)" |
string
|
— |
PATHExecutable search path |
"" |
string
|
— |
NODE_MODULES_DIRShared Node.js module resolution root |
"" |
string
|
— |
NODE_MODULE_DIRLegacy alias for NODE_MODULES_DIR |
"" |
string
|
— |
NODE_PATHNode.js module lookup path |
"" |
string
|
— |
NODE_V8_COVERAGEOptional V8 coverage output directory for Node.js hooks |
"" |
string
|
— |
Claude Code
claudecode
Run Claude Code AI agent on snapshots to extract, analyze, or transform archived content.
Embed
Fullscreen
node (env,node,apt,brew)
claude (env,pnpm)
application/json
Claude Code
claudecodeRun Claude Code AI agent on snapshots to extract, analyze, or transform archived content.
Embed
Fullscreen
node (env,node,apt,brew)
claude (env,pnpm)
application/json
Run Claude Code AI agent on snapshots to extract, analyze, or transform archived content.
GitHubabx-dl plugins claudecodearchivebox add 'https://example.com'Utility plugins are typically consumed indirectly, so the example shows the closest inspection workflow.
node
providers=env,node,apt,brew
claude
providers=env,pnpm
No hook scripts.
application/json
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
NODE_BINARYPath to Node.js binary |
"node" |
string
|
— |
CLAUDECODE_ENABLEDEnable Claude Code AI agent integration. Controls whether the Claude CLI dependency is resolved for this plugin; child plugins still need the claudecode plugin enabled and a working Claude binary. |
false |
boolean
|
USE_CLAUDECODE |
CLAUDECODE_BINARYPath to Claude Code CLI binary |
"claude" |
string
|
— |
CLAUDECODE_TIMEOUTTimeout for Claude Code operations in seconds |
120 |
integer
min 10 |
fallback: TIMEOUT |
ANTHROPIC_API_KEYAnthropic API key for Claude Code authentication |
"" |
string
|
— |
CLAUDE_CODE_OAUTH_TOKENClaude Code OAuth token for Claude Code authentication |
"" |
string
|
— |
CLAUDECODE_MODELClaude model to use (e.g. claude-sonnet-4-6, claude-opus-4-6, claude-haiku-4-5-20251001) |
"claude-sonnet-4-6" |
string
|
— |
CLAUDECODE_MAX_TURNSMaximum number of agentic turns per invocation |
50 |
integer
min 1 |
— |
Media
media
Provide a shared namespace for media-related plugin outputs and helpers.
Media
mediaProvide a shared namespace for media-related plugin outputs and helpers.
Provide a shared namespace for media-related plugin outputs and helpers.
GitHubabx-dl plugins mediaarchivebox add 'https://example.com'Utility plugins are typically consumed indirectly, so the example shows the closest inspection workflow.
None
No hook scripts.
None
This plugin does not define a
config.json schema.
OpenCode Agent
opencode
Expose an admin-only embedded OpenCode web agent UI for ArchiveBox.
node (env,node,apt,brew)
npm (env,node,apt,brew)
+2 more
OpenCode Agent
opencodeExpose an admin-only embedded OpenCode web agent UI for ArchiveBox.
node (env,node,apt,brew)
npm (env,node,apt,brew)
+2 more
Expose an admin-only embedded OpenCode web agent UI for ArchiveBox.
GitHubabx-dl plugins opencodearchivebox add 'https://example.com'Utility plugins are typically consumed indirectly, so the example shows the closest inspection workflow.
node
providers=env,node,apt,brew
npm
providers=env,node,apt,brew
git
providers=env,apt,brew
opencode
providers=env,pnpm
min_version=1.18.31
No hook scripts.
None
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
NODE_BINARYPath to Node.js binary |
"node" |
string
|
— |
NPM_BINARYPath to npm binary used by OpenCode postinstall to fetch the platform CLI package |
"npm" |
string
|
— |
GIT_BINARYPath to Git binary used by OpenCode to inspect existing projects; ArchiveBox never initializes a repository |
"git" |
string
|
— |
OPENCODE_ENABLEDEnable the admin-only /admin/agent OpenCode web UI route |
false |
boolean
|
— |
OPENCODE_BINARYPath to OpenCode CLI binary |
"opencode" |
string
|
— |
OPENCODE_HOSTHost for the local OpenCode web server |
"127.0.0.1" |
string
|
— |
OPENCODE_PORTPort for the local OpenCode web server |
4096 |
integer
min 1 |
— |
OPENCODE_WORKDIRWorking directory for OpenCode. Defaults to DATA_DIR; no Git repository is created and checkpointing is disabled by default |
"" |
string
|
— |
OPENCODE_STATE_DIRDirectory for OpenCode config, state, cache, sessions, and editable ArchiveBox skill at SKILL.md. Defaults to DATA_DIR/opencode |
"" |
string
|
— |
OPENCODE_TIMEOUTSeconds to wait for OpenCode startup and proxied requests, including cold provider catalog loading |
120 |
integer
min 1 |
— |
ripgrep Search
search_backend_ripgrep
Search archived snapshot files directly with ripgrep instead of maintaining an index.
rg (env,apt,brew)
ripgrep Search
search_backend_ripgrepSearch archived snapshot files directly with ripgrep instead of maintaining an index.
rg (env,apt,brew)
Search archived snapshot files directly with ripgrep instead of maintaining an index.
GitHubabx-dl plugins search_backend_ripgreparchivebox add 'https://example.com'Utility plugins are typically consumed indirectly, so the example shows the closest inspection workflow.
rg
providers=env,apt,brew
No hook scripts.
None
| Configuration Option | Default | Type | Aliases / Fallback |
|---|---|---|---|
SEARCH_BACKEND_RIPGREP_ENABLEDSearch archived snapshot files directly with ripgrep. |
true |
boolean
|
— |
RIPGREP_BINARYPath to ripgrep binary |
"rg" |
string
|
— |
RIPGREP_TIMEOUTSearch timeout in seconds |
90 |
integer
min 1 |
SEARCH_BACKEND_TIMEOUT, SEARCH_BACKEND_RIPGREP_TIMEOUT fallback: TIMEOUT |
RIPGREP_ARGSDefault ripgrep arguments |
[ "--files-with-matches" "--no-messages" "--ignore-case" |
array
|
RIPGREP_DEFAULT_ARGS |
RIPGREP_ARGS_EXTRAExtra arguments to append to ripgrep command |
[] |
array
|
RIPGREP_EXTRA_ARGS |
SSL
ssl
Utility plugin namespace reserved for SSL-related integration points and metadata.
SSL
sslUtility plugin namespace reserved for SSL-related integration points and metadata.
Utility plugin namespace reserved for SSL-related integration points and metadata.
GitHubabx-dl plugins sslarchivebox add 'https://example.com'Utility plugins are typically consumed indirectly, so the example shows the closest inspection workflow.
None
No hook scripts.
None
This plugin does not define a
config.json schema.No plugins match the current filter.